Operations improves when the stack can explain itself.
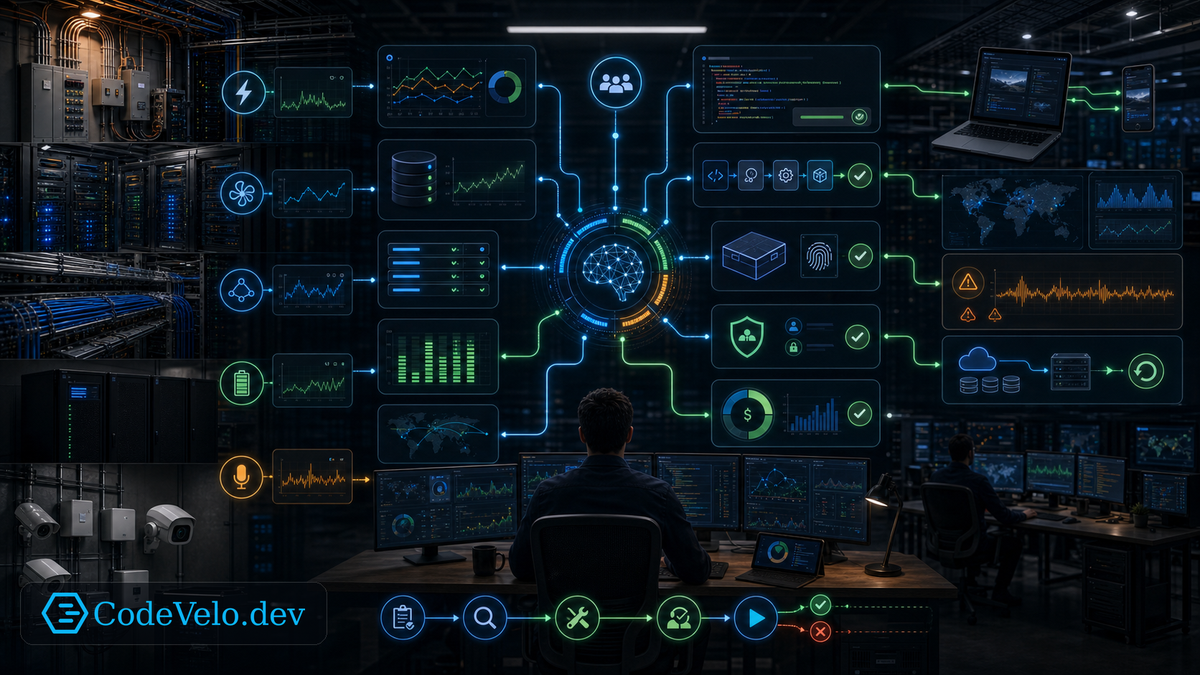
That means measuring more than uptime. It means connecting physical telemetry, application behavior, cost, capacity, privacy, deployment evidence, and recovery paths. A measured stack helps teams know what changed, what it costs, what it affects, and what to do next.
This is the August checklist.
1. Measure Physical Conditions
Review server room sensors, power quality data, UPS events, airflow, acoustic patterns, and rack temperature zones.
The goal is to understand the room as a system. One sensor is a signal. Correlated sensors are context.
2. Track Capacity Across Layers
Capacity should include ports, PoE, cooling, UPS runtime, rack space, IP space, edge compute, database headroom, and frontend rendering budgets.
If one layer is exhausted, the system is constrained even when other layers look healthy.
3. Contract The Telemetry
Events, metrics, logs, traces, and RUM data should have owners and schemas.
Define names, fields, units, privacy classification, cardinality limits, and versioning. Telemetry that cannot be trusted cannot guide operations.
4. Preserve Operational Evidence
Fiber paths, asset lifecycle, database changes, feature flag state, build artifacts, and deployment approvals should all leave records.
Evidence turns incidents and audits into engineering work instead of archaeology.
5. Protect Privacy And Trust
Measure enough to operate the product, not enough to expose users unnecessarily.
Review RUM collection, access controls, retention, redaction, and vendor paths. Good observability should make the product safer, not more invasive.
6. Make Recovery Visible
Run rooms, rollback paths, backup procedures, and operational controls should be ready before the outage.
The measured stack is not just about dashboards. It is about knowing which action comes next.