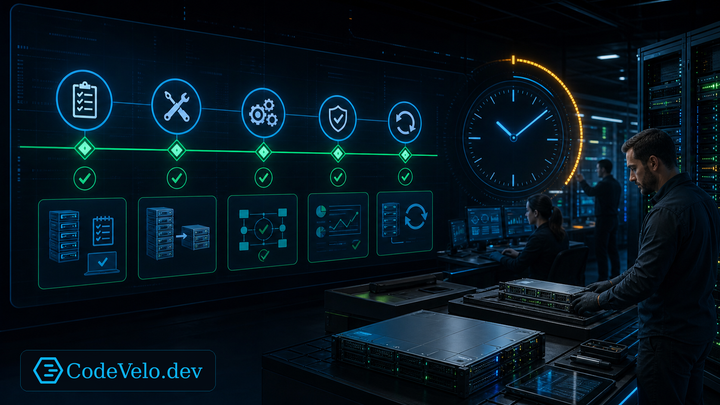
Maintenance Windows as a Designed Operational Product
A good maintenance window has a clear customer promise, tested procedure, decision authority, telemetry, and recovery path.
Topic
A good maintenance window has a clear customer promise, tested procedure, decision authority, telemetry, and recovery path.
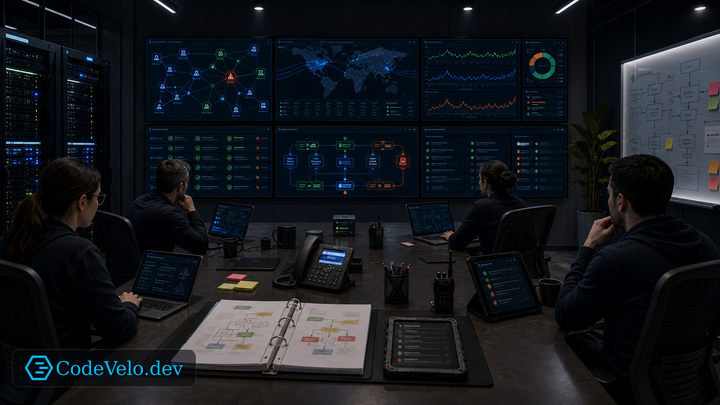
The best incident room is not chaotic. It is a prepared run room with maps, authority, telemetry, and recovery paths ready before the outage.
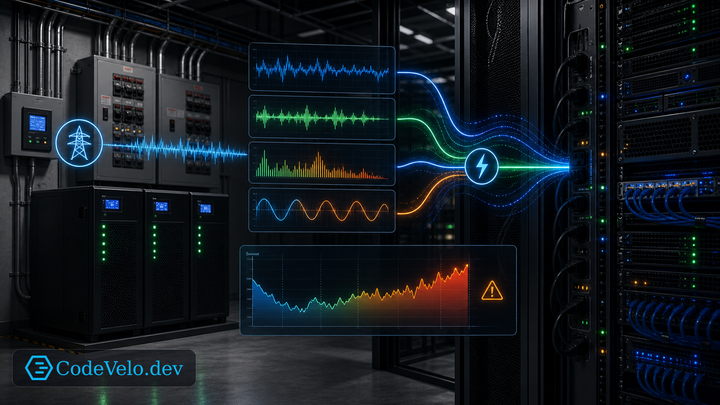
Power quality data can reveal stress before a full outage. Voltage, harmonics, transfer events, and UPS behavior should be part of infrastructure telemetry.
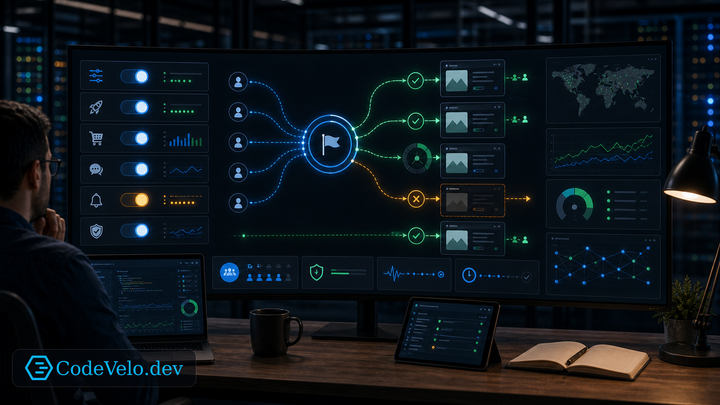
Feature flags are not only release tools. They are operational controls that shape blast radius, recovery, and real-time product behavior.
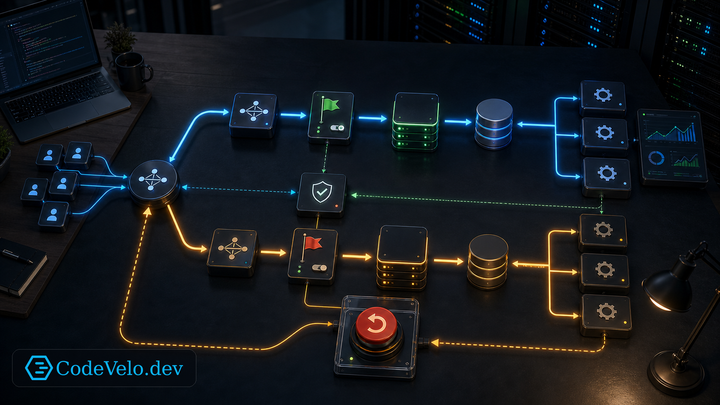
A rollback-first architecture treats recovery as a design requirement, not a hopeful button added after deployment.
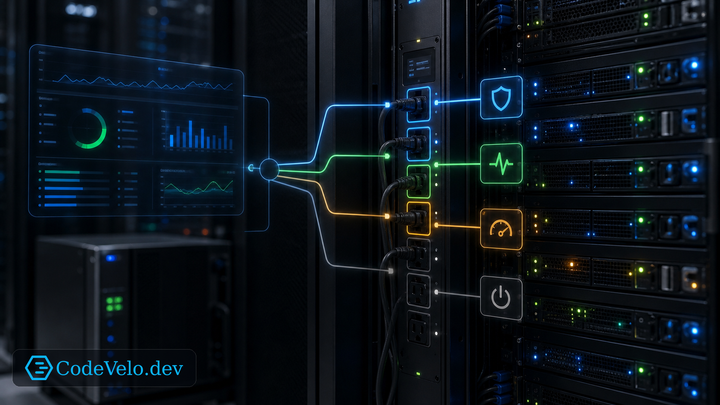
Smart PDUs become more valuable when power control is tied to policy, priority, and recovery order instead of ad hoc remote clicks.
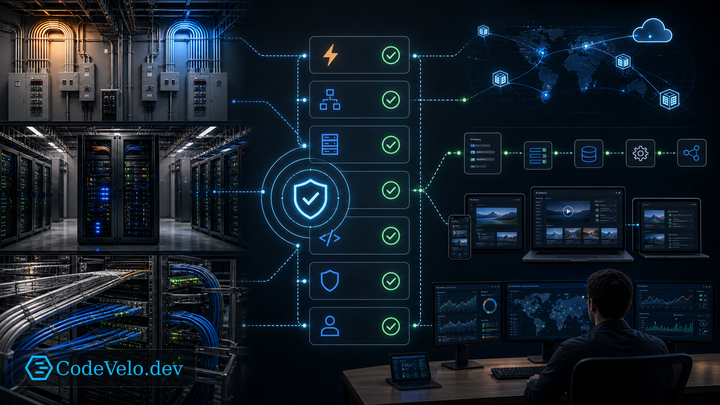
A practical hardening checklist that connects the physical layer, the network, the application, and the browser into one resilience review.
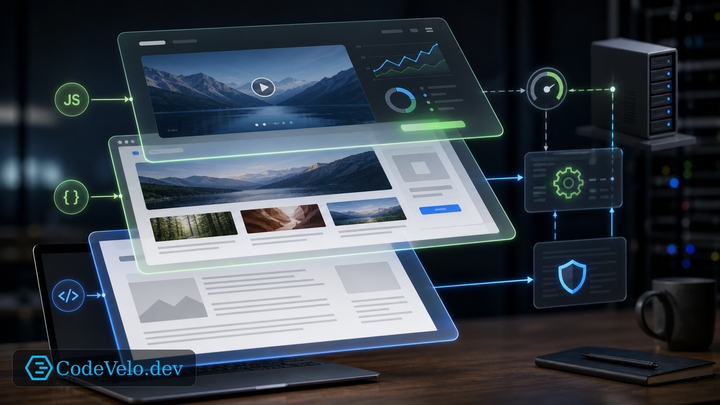
Zero-JS is not nostalgia. It is the baseline that lets modern apps keep working when JavaScript, hydration, or edge personalization fails.
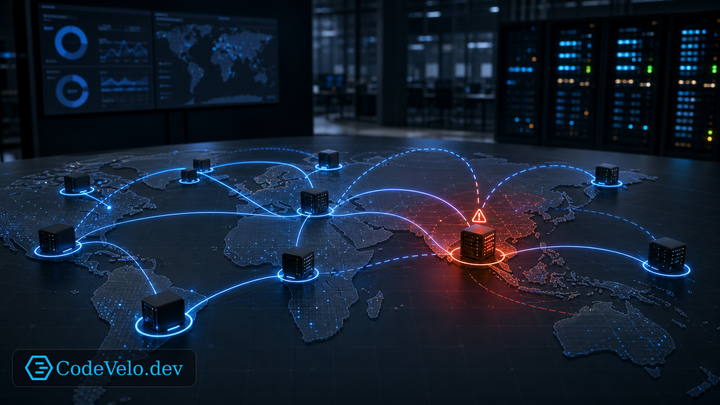
Edge systems fail differently than centralized apps. Chaos testing has to include regional outages, stale islands, cache disagreement, and partial user experiences.